
Can evolution be the Master Algorithm?
Fun AutoML-Zero experiments: Evolutionary search discovers fundamental ML algorithms from scratch, e.g., small neural nets with backprop.
Genetic programming learned operations reminiscent of dropout, normalized gradients, and weight averaging when trying to evolve better learning algorithms.
Paper: https://arxiv.org/abs/2003.03384
Code: https://git.io/JvKrZ
#automl #genetic
Team
@OpenArchiveBooks
@data_enthusiasts
If you feel our channel can be beneficial for others then please spread the word among other students.
https://t.me/data_enthusiasts
Let's create a healthy Data Science community where we can work on models, ideas and other relevant stuff.
https://t.me/data_enthusiasts
Let's create a healthy Data Science community where we can work on models, ideas and other relevant stuff.
A Deep Learning Approach to Antibiotic Discovery
A new antibiotic was found using DL, claimed to be effective against several bacteria resistant to existing antibiotics on mice in the lab.
The problem with finding good antibiotics is potential molecule space is prohibitively large to test all possible molecules in the lab. They train a model that receives the molecule as a graph and tries to predict how effective it is against E. coli.
For every edge, they run single-layer NN receiving activations and features of input node and edge features, and producing new activations for the edge. Activations of the node = sum of all incoming edge activations. Overall activations vector for molecule = sum of all nodes.
Finally, there's a 2-layer NN receiving overall vector for the molecule + some standard handcrafted features with a binary classification output, trained end-to-end on 2.3K molecules. Then, they predict on the dataset of 6K molecules being in different stages of the investigation.
They looked at the top 51 predictions and manually ranked them by not being similar to the training dataset, being far in the investigation stage and scoring low on the external toxicity model. The top pick is what they called Halicin and tested in the lab.
article (only pdf): https://www.cell.com/cell/pdf/S0092-8674(20)30102-1.pdf
#medicine #molecule #antibiotic #dl #graph
Team
@OpenArchiveBooks
@data_enthusiasts

This media is not supported in your browser
VIEW IN TELEGRAM
Music Conditioned 3D Dance Generation with AIST++
Blog: https://ai.googleblog.com/2021/09/music-conditioned-3d-dance-generation.html
Code: https://github.com/google-research/mint
AI Model: https://drive.google.com/drive/folders/17GHwKRZbQfyC9-7oEpzCG8pp_rAI0cOm?usp=sharing
#artificialintelligence
Team
@OpenArchiveBooks
@data_enthusiasts
Blog: https://ai.googleblog.com/2021/09/music-conditioned-3d-dance-generation.html
Code: https://github.com/google-research/mint
AI Model: https://drive.google.com/drive/folders/17GHwKRZbQfyC9-7oEpzCG8pp_rAI0cOm?usp=sharing
#artificialintelligence
Team
@OpenArchiveBooks
@data_enthusiasts
Data Scientists Without Data Engineering Skills Will Face the Harsh Truth
https://towardsdatascience.com/data-scientists-without-data-engineering-skills-will-face-the-harsh-truth-ff482a223ddc
#dataengineering #datascience
Team
@OpenArchiveBooks
@data_enthusiasts
https://towardsdatascience.com/data-scientists-without-data-engineering-skills-will-face-the-harsh-truth-ff482a223ddc
#dataengineering #datascience
Team
@OpenArchiveBooks
@data_enthusiasts
Medium
Data Scientists Without Data Engineering Skills Will Face the Harsh Truth
Get yourself ready for the real world.
A friendly introduction to machine learning compilers and optimizers
https://huyenchip.com/2021/09/07/a-friendly-introduction-to-machine-learning-compilers-and-optimizers.html
#beginner #datascience #machinelearning
Team
@OpenArchiveBooks
@data_enthusiasts
https://huyenchip.com/2021/09/07/a-friendly-introduction-to-machine-learning-compilers-and-optimizers.html
#beginner #datascience #machinelearning
Team
@OpenArchiveBooks
@data_enthusiasts
Chip Huyen
A friendly introduction to machine learning compilers and optimizers
[Twitter thread, Hacker News discussion]
What is Trending on Wikipedia? Capturing Trends and Language Biases Across Wikipedia Editions
The authors propose an automatic evaluation and comparison of the browsing behavior of Wikipedia readers that can be applied to any language editions of Wikipedia. Focused on English, French, and Russian languages during the last four months of 2018.
They approach consists of the following steps:
– extraction of a sub-network of trending Wikipedia articles and identification of trends
– extraction of keywords from the summaries of every Wikipedia article in the sub-network and weighting according to their importance
– labeling of the trends with high-level topics using the extracted keywords
Paper: https://arxiv.org/pdf/2002.06885
Code: https://github.com/epfl-lts2/sparkwiki
#nlp #trend #wikipedia
Team
@OpenArchiveBooks
@data_enthusiasts

Photofeeler-D3
tl;dr: predict first impressions from a photo or video
some interesting items of note:
- notice how Smart is the dominant trait until he takes off his glasses
- when the glasses are taken off, his Attractive score rises
- there’s a quick dip in scores every time he blinks
- the overall top scores result from the genuine smile at the very end!
Blog post: https://blog.photofeeler.com/photofeeler-d3/
Paper: https://arxiv.org/pdf/1904.07435
Demo: available to the researchers on the request
#cv #dl #impression
Team
@OpenArchiveBooks
@data_enthusiasts
This media is not supported in your browser
VIEW IN TELEGRAM
AnimeGANv2 Face Portrait v2
Convert Face Portraits into Anime
github: https://github.com/bryandlee/animegan2-pytorch
huggingface gradio demo: https://huggingface.co/spaces/akhaliq/AnimeGANv2
gradio github: https://github.com/gradio-app/gradio
huggingface spaces: https://huggingface.co/spaces
Team
@OpenArchiveBooks
@data_enthusiasts
How to avoid Machine learning pitfalls a guide to academic researchers
https://arxiv.org/pdf/2108.02497.pdf
Team
@OpenArchiveBooks
@data_enthusiasts
https://arxiv.org/pdf/2108.02497.pdf
Team
@OpenArchiveBooks
@data_enthusiasts
How to Solve a Staff Scheduling Problem with Python
https://towardsdatascience.com/how-to-solve-a-staff-scheduling-problem-with-python-63ae50435ba4
#Python #DS
Team
@OpenArchiveBooks
@data_enthusiasts
https://towardsdatascience.com/how-to-solve-a-staff-scheduling-problem-with-python-63ae50435ba4
#Python #DS
Team
@OpenArchiveBooks
@data_enthusiasts
Medium
How to Solve a Staff Scheduling Problem with Python
Minimize the number of workers per shift while assigning enough workers for each time window
Data Scientist, Data Engineer & Other Data Careers, Explained
https://www.kdnuggets.com/2021/05/data-scientist-data-engineer-data-careers-explained.html
#datascience #machinelearning
Team
@OpenArchiveBooks
@data_enthusiasts
https://www.kdnuggets.com/2021/05/data-scientist-data-engineer-data-careers-explained.html
#datascience #machinelearning
Team
@OpenArchiveBooks
@data_enthusiasts
KDnuggets
Data Scientist, Data Engineer & Other Data Careers, Explained
In this article, we will have a look at five distinct data careers, and hopefully provide some advice on how to get one's feet wet in this convoluted field.
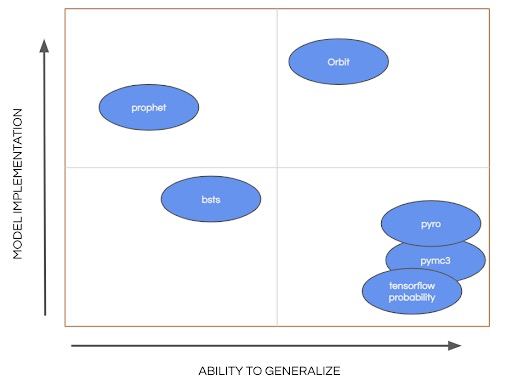
Orbit — An Open Source Package for Time Series Inference and Forecasting
Object-ORiented BayesIan Time Series is a new project for #timeseries forecasting by #Uber team. Has #scikit-learn compatible interface and claimed to have results comparable to #prophet .
Post: https://eng.uber.com/orbit/
Docs: https://uber.github.io/orbit/about.html
Code: https://github.com/uber/orbit/
Team
@OpenArchiveBooks
@data_enthusiasts
AR PIONEER WARNS THAT METAVERSE COULD MAKE “REALITY DISAPPEAR”
Article: https://futurism.com/the-byte/ar-pioneer-warns-metaverse
Team
@OpenArchiveBooks
@data_enthusiasts
Article: https://futurism.com/the-byte/ar-pioneer-warns-metaverse
Team
@OpenArchiveBooks
@data_enthusiasts
THE_BYTE.
AR Pioneer Warns That Metaverse Could Make "Reality Disappear"
An innovator in early AR systems has a dire prediction: the metaverse could destroy reality as we know it.
What if I am not Good Programmer?
Programming is a integral part of Artificial intelligence but AI or Machine learning is much larger than just programming.
You do not always have to be a programmer to get started in machine learning or find solutions to Machine learning, Data science complex problems.
Checkout, No code platforms!
https://mobile.twitter.com/Aiindiaai/status/1454097323462565898
Team
@OpenArchiveBooks
@data_enthusiasts
This media is not supported in your browser
VIEW IN TELEGRAM
Reading research papers is no doubt the Best way to Stay up to date in the fields like Artificial Intelligence, Machine Learning, and Deep Learning that are always evolving at fast pace.
"You have to equip yourselves with the knowledge to keep up with the field, knowledge that is only attainable through research papers. To stay relevant and increase knowledge, machine learning practitioners need to have an academic mindset and habit."
Team
@OpenArchiveBooks
@data_enthusiasts
"You have to equip yourselves with the knowledge to keep up with the field, knowledge that is only attainable through research papers. To stay relevant and increase knowledge, machine learning practitioners need to have an academic mindset and habit."
Team
@OpenArchiveBooks
@data_enthusiasts
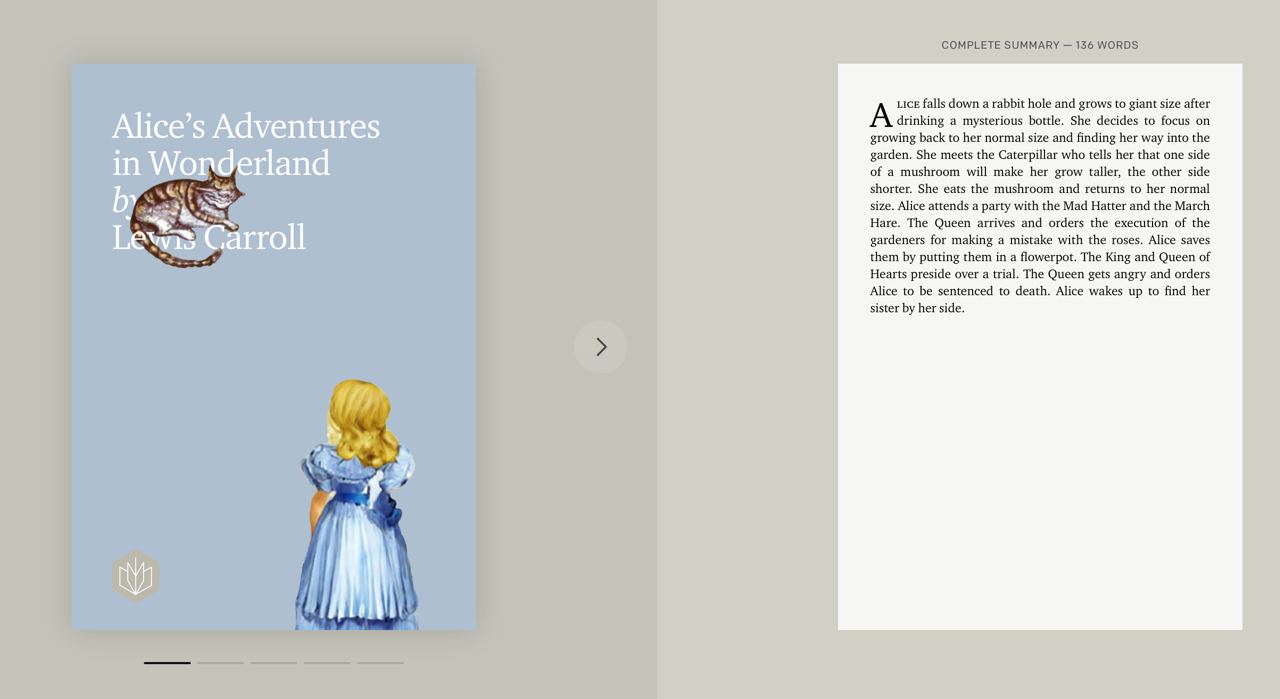
Summarizing Books with Human Feedback
#OpenAI fine-tuned #GPT3 to summarize books well enough to be human-readable. Main approach: recursively split text into parts and then meta-summarize summaries.
This is really important because once there will be a great summarization #SOTA we won't need editors to write posts for you. And researchers ultimatively will have some asisstance interpreting models' results.
BlogPost: https://openai.com/blog/summarizing-books/
Paper: https://arxiv.org/pdf/2109.10862
#summarization #NLU #NLP
Team
@OpenArchiveBooks
@data_enthusiasts
If you find our channel helpful then please share it with other students from this degree.
https://t.me/data_enthusiasts
'If you want to go fast, go alone. If you want to go far, go together. '
Let's create a healthy community and help each other excel in this field.
(If anyone wants to help us with interesting AI and ML projects and research papers then do let us know in our discussion chat)
Team
@OpenArchiveBooks
@data_enthusiasts