Ensemble Methods: Elegant Techniques to Produce Improved Machine Learning Results
In this paper, the author discusses some elegant techniques of ensemble methods, which utilize a combination of data partitioning and multiple algorithms to produce machine learning results with higher accuracy.
Read...
In this paper, the author discusses some elegant techniques of ensemble methods, which utilize a combination of data partitioning and multiple algorithms to produce machine learning results with higher accuracy.
Read...
Tree Kernels: Quantifying Similarity Among Tree-structured Data
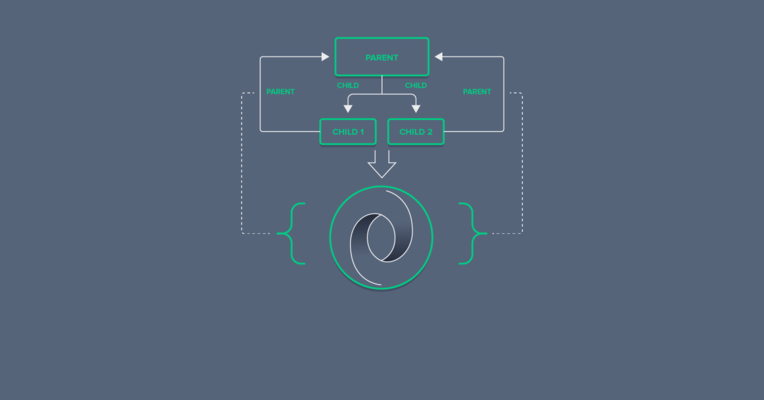
In this article, we will look at the analysis of the link structure in trees. In particular, we will focus on tree kernels, a method for comparing tree graphs to each other, allowing us to get quantifiable measurements of their similarities or differences.
Read...
In this article, we will look at the analysis of the link structure in trees. In particular, we will focus on tree kernels, a method for comparing tree graphs to each other, allowing us to get quantifiable measurements of their similarities or differences.
Read...
🖕1

🧰 How agents work with MCP and identify a problem? (By Microsoft)
When there are too many tools, agents start interfering with each other. This was called tool-space interference.
🔵 How it manifests?
- overloaded tool menus
- excessively large outputs
- confusing parameters
- duplicate names
- vague errors
🟤 What comes In the study?
🟢 What is the Solutions from Microsoft?
Fewer tools, Cleaner parameters, Structured responses = agents start cooperating rather than getting in each other's way.
🤖 Data Science, ML & Big Data with @DataXplore
When there are too many tools, agents start interfering with each other. This was called tool-space interference.
🔵 How it manifests?
- overloaded tool menus
- excessively large outputs
- confusing parameters
- duplicate names
- vague errors
🟤 What comes In the study?
- Some servers offered up to 256 tools, although the optimal number is fewer than 20. With large menus, accuracy dropped by 85%.
- One tool returned an average of 557,766 tokens per response, 16 tools returned more than 128,000 tokens. This broke models and reduced accuracy by 91%.
- Deeply nested parameters (up to 20 levels) hindered performance. Flattening the schema increased success by 47%.
- 775 duplicate tool names were found, the word "search" appeared in 32 servers.
🟢 What is the Solutions from Microsoft?
- group tools into smaller sets
- cache schemas
- use namespaces for unique names
- limit response sizes and simplify parameters
- standardize errors and support resource passing
📊 Reports show that smart use of namespaces sped up task execution by 40%.
Fewer tools, Cleaner parameters, Structured responses = agents start cooperating rather than getting in each other's way.
🤖 Data Science, ML & Big Data with @DataXplore
❤2🔥2🤔1