
Paper «A Probabilistic U-Net for Segmentation of Ambiguous Images» from #NIPS2018 spotlight presentation.
Github: https://github.com/SimonKohl/probabilistic_unet
Github: Arxiv: https://arxiv.org/abs/1806.05034
#DeepMind #segmentation #cv
Github: https://github.com/SimonKohl/probabilistic_unet
Github: Arxiv: https://arxiv.org/abs/1806.05034
#DeepMind #segmentation #cv
GitHub
GitHub - SimonKohl/probabilistic_unet: A U-Net combined with a variational auto-encoder that is able to learn conditional distributions…
A U-Net combined with a variational auto-encoder that is able to learn conditional distributions over semantic segmentations. - GitHub - SimonKohl/probabilistic_unet: A U-Net combined with a variat...
#DeepMind ’s library for deep learning on graphs.
ArXiV: https://arxiv.org/abs/1806.01261
Github: https://github.com/deepmind/graph_nets
ArXiV: https://arxiv.org/abs/1806.01261
Github: https://github.com/deepmind/graph_nets
GitHub
GitHub - google-deepmind/graph_nets: Build Graph Nets in Tensorflow
Build Graph Nets in Tensorflow. Contribute to google-deepmind/graph_nets development by creating an account on GitHub.
🎓 Free «Advanced Deep Learning and Reinforcement Learning» course.
#DeepMind researchers have released video recordings of lectures from «Advanced Deep Learning and Reinforcement Learning» a course on deep RL taught at #UCL earlier this year.
YouTube Playlist: https://www.youtube.com/playlist?list=PLqYmG7hTraZDNJre23vqCGIVpfZ_K2RZs
#course #video #RL #DL
#DeepMind researchers have released video recordings of lectures from «Advanced Deep Learning and Reinforcement Learning» a course on deep RL taught at #UCL earlier this year.
YouTube Playlist: https://www.youtube.com/playlist?list=PLqYmG7hTraZDNJre23vqCGIVpfZ_K2RZs
#course #video #RL #DL
🔥 AlphaFold: Using AI for scientific discovery.
#DeepMind has significally improved protein folding prediction.
Protein folding is important because it allows to predict function along with the functioning mechanism.
Website: https://deepmind.com/blog/alphafold/
Guardian: https://www.theguardian.com/science/2018/dec/02/google-deepminds-ai-program-alphafold-predicts-3d-shapes-of-proteins
#bioinformatics #alphafold #genetics
Papers from #DeepMind panel at #NIPS2018
Work on radiotherapy planning: https://arxiv.org/abs/1809.04430
Triaging eye diseases: https://www.nature.com/articles/s41591-018-0107-6
Probabilistic U-net: https://arxiv.org/abs/1806.05034
#segmentation #CV #Unet
Work on radiotherapy planning: https://arxiv.org/abs/1809.04430
Triaging eye diseases: https://www.nature.com/articles/s41591-018-0107-6
Probabilistic U-net: https://arxiv.org/abs/1806.05034
#segmentation #CV #Unet
#DeepMind will show AI playing #Starcraft II.
Starts in 8 hours (6:00 PM GMT)
youtube.com/c/deepmind / https://www.twitch.tv/starcraft
#RL
Starts in 8 hours (6:00 PM GMT)
youtube.com/c/deepmind / https://www.twitch.tv/starcraft
#RL
Large Scale Adversarial Representation Learning
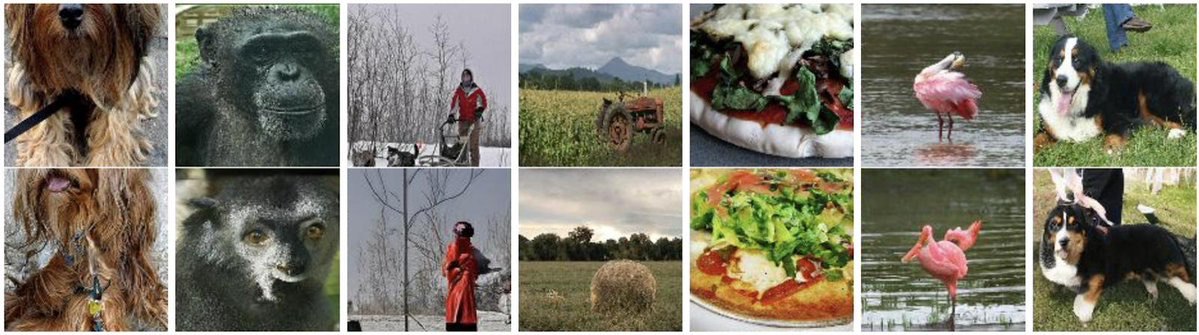
DeepMind shows that GANs can be harnessed for unsupervised representation learning, with state-of-the-art results on ImageNet. Reconstructions, as shown in paper, tend to emphasise high-level semantics over pixel-level details.
Link: https://arxiv.org/abs/1907.02544
#DeepMind #GAN #CV #DL #SOTA
DeepMind shows that GANs can be harnessed for unsupervised representation learning, with state-of-the-art results on ImageNet. Reconstructions, as shown in paper, tend to emphasise high-level semantics over pixel-level details.
Link: https://arxiv.org/abs/1907.02544
#DeepMind #GAN #CV #DL #SOTA
DeepMind's Behaviour Suite for Reinforcement Learning
DeepMind released Behaviour Suite for Reinforcement Learning, or ‘bsuite’ – a collection of carefully-designed experiments that investigate core capabilities of RL agents.
bsuite was built to do two things:
1. Offer clear, informative, and scalable experiments that capture key issues in RL
2. Study agent behaviour through performance on shared benchmarks
GitHub: https://github.com/deepmind/bsuite
Paper: https://arxiv.org/abs/1908.03568v1
Google colab: https://colab.research.google.com/drive/1rU20zJ281sZuMD1DHbsODFr1DbASL0RH
#RL #DeepMind #Bsuite
GitHub
GitHub - google-deepmind/bsuite: bsuite is a collection of carefully-designed experiments that investigate core capabilities of…
bsuite is a collection of carefully-designed experiments that investigate core capabilities of a reinforcement learning (RL) agent - google-deepmind/bsuite
Applying machine learning optimization methods to the production of a quantum gas
#DeepMind developed machine learning techniques to optimise the production of a Bose-Einstein condensate, a quantum-mechanical state of matter that can be used to test predictions of theories of many-body physics.
ArXiV: https://arxiv.org/abs/1908.08495
#Physics #DL #BEC
#DeepMind developed machine learning techniques to optimise the production of a Bose-Einstein condensate, a quantum-mechanical state of matter that can be used to test predictions of theories of many-body physics.
ArXiV: https://arxiv.org/abs/1908.08495
#Physics #DL #BEC
🔥DeepMind’s AlphaStar beats top human players at strategy game StarCraft II
AlphaStar by Google’s DeepMind can now play StarCraft 2 so well that it places in the 99.8 percentile on the European server. In other words, way better than even great human players, achieving performance similar to gods of StarCraft.
Solution basically combines reinforcement learning with a quality-diversity algorithm, which is similar to an evolutionary algorithm.
What’s difficult about StarCraft and how is it different to recent #Go and #Chess AI solutions: even finding winning strategy (StarCraft is famouse to closeness to rock-scissors-paper, not-so-transitive game design, as chess and go), is not enough to win, since the result depends on execution on different macro and micro levels at different timescales.
How that is applicable in real world: basically, it is running logistics, manufacture, research with complex operations and different units.
Why this matters: it brings AI one step closer to running real business.
Blog post: https://deepmind.com/blog/article/AlphaStar-Grandmaster-level-in-StarCraft-II-using-multi-agent-reinforcement-learning
Nature: https://www.nature.com/articles/d41586-019-03298-6
ArXiV: https://arxiv.org/abs/1902.01724
Nontechnical video: https://www.youtube.com/watch?v=6eiErYh_FeY
#Google #GoogleAI #AlphaStar #Starcraft #Deepmind #nature #AlphaZero
YouTube
The AI that mastered Starcraft II
Google’s DeepMind artificial intelligence researchers have already mastered games like Pong, Chess and Go but their latest triumph is on another planet. AlphaStar is an artificial intelligence trained to play the science fiction video game StarCraft II.
…
…
LOGAN: Latent Optimisation for Generative Adversarial Networks
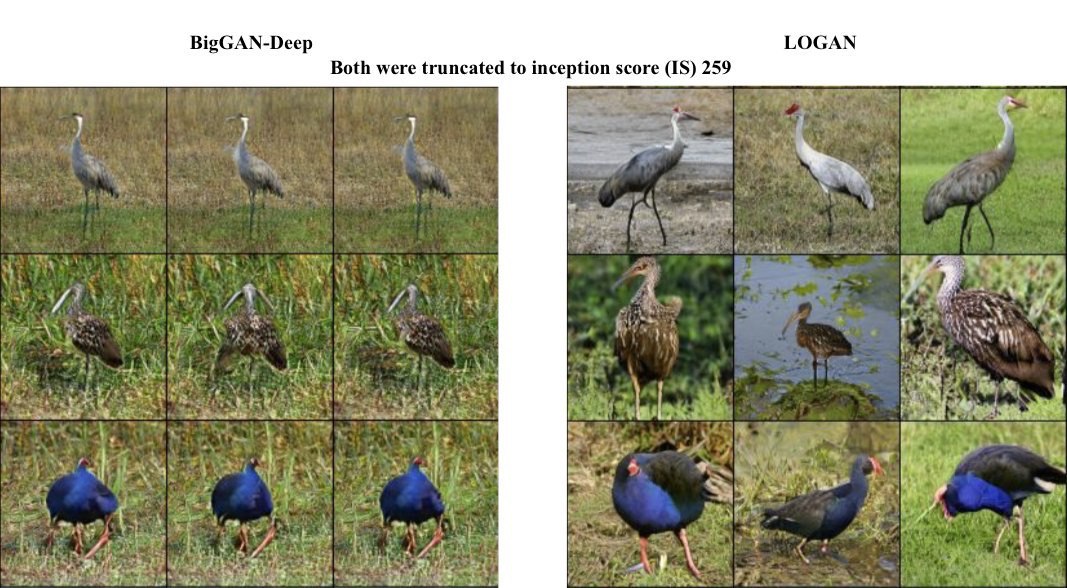
Game-theory motivated algorithm from #DeepMind improves the state-of-the-art in #GAN image generation by over 30% measured in FID.
ArXiV: https://arxiv.org/abs/1912.00953
Game-theory motivated algorithm from #DeepMind improves the state-of-the-art in #GAN image generation by over 30% measured in FID.
ArXiV: https://arxiv.org/abs/1912.00953
Dream to Control: Learning Behaviors by Latent Imagination
Abstract: Learned world models summarize an agent's experience to facilitate learning complex behaviors. While learning world models from high-dimensional sensory inputs are becoming feasible through deep learning, there are many potential ways for deriving behaviors from them. We present Dreamer, a reinforcement learning agent that solves long-horizon tasks from images purely by latent imagination. We efficiently learn behaviors by propagating analytic gradients of learned state values back through trajectories imagined in the compact state space of a learned world model. On 20 challenging visual control tasks, Dreamer exceeds existing approaches in data-efficiency, computation time, and final performance.
Dreamer learns long-horizon behaviors from images purely by latent imagination. For this, it backpropagates value estimates through trajectories imagined in the compact latent space of a learned world model. Dreamer solves visual control tasks using substantially fewer episodes than strong model-free agents.
Dreamer learns a world model from past experiences that can predict the future. It then learns action and value models in its compact latent space. The value model optimizes Bellman's consistency of imagined trajectories. The action model maximizes value estimates by propagating their analytic gradients back through imagined trajectories. When interacting with the environment, it simply executes the action model.
paper: https://arxiv.org/abs/1912.01603
github: https://github.com/google-research/dreamer
site: https://danijar.com/dreamer
#RL #Dreams #Imagination #DL #GoogleBrain #DeepMind
👍1
A Deep Neural Network's Loss Surface Contains Every Low-dimensional Pattern
New work from #DeepMind built in top of Loss Landscape Sightseeing with Multi-Point Optimization
ArXiV: https://arxiv.org/abs/1912.07559
Predecessor’s github: https://github.com/universome/loss-patterns
New work from #DeepMind built in top of Loss Landscape Sightseeing with Multi-Point Optimization
ArXiV: https://arxiv.org/abs/1912.07559
Predecessor’s github: https://github.com/universome/loss-patterns
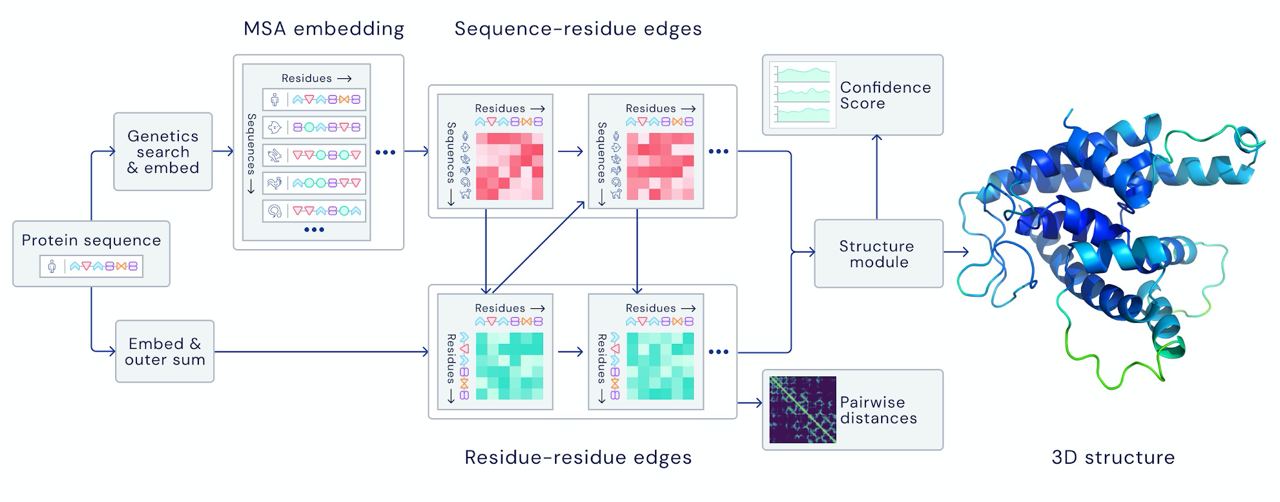
DeepMind significally (+100%) improved protein folding modelling
Why is this important: protein folding = protein structure = protein function = how protein works in the living speciment and what it does.
What this means: better vaccines, better meds, more curable diseases and more calamities easen by the medications or better understanding.
Dataset: ~170000 available protein structures from PDB
Hardware: 128 TPUv3 cores (roughly equivalent to ~100-200 GPUs)
Link: https://deepmind.com/blog/article/alphafold-a-solution-to-a-50-year-old-grand-challenge-in-biology
#DL #NLU #proteinmodelling #bio #biolearning #insilico #deepmind #AlphaFold
Protein Folding explained
#deepmind didn’t stop at delivering the improved technology for folding #proteinfolding . They also provided really cool video explaining why is that so cool.
YouTube: https://www.youtube.com/watch?v=KpedmJdrTpY&feature=emb_title
#explained #bio #proteinmodelling
#deepmind didn’t stop at delivering the improved technology for folding #proteinfolding . They also provided really cool video explaining why is that so cool.
YouTube: https://www.youtube.com/watch?v=KpedmJdrTpY&feature=emb_title
#explained #bio #proteinmodelling
YouTube
Protein folding explained
Join DeepMind Science Engineer Kathryn Tunyasuvunakool to explore the hidden world of proteins.
These tiny molecular machines underpin every biological process in every living thing and each one has a unique 3D shape that determines how it works and what…
These tiny molecular machines underpin every biological process in every living thing and each one has a unique 3D shape that determines how it works and what…
Solving Mixed Integer Programs Using Neural Networks
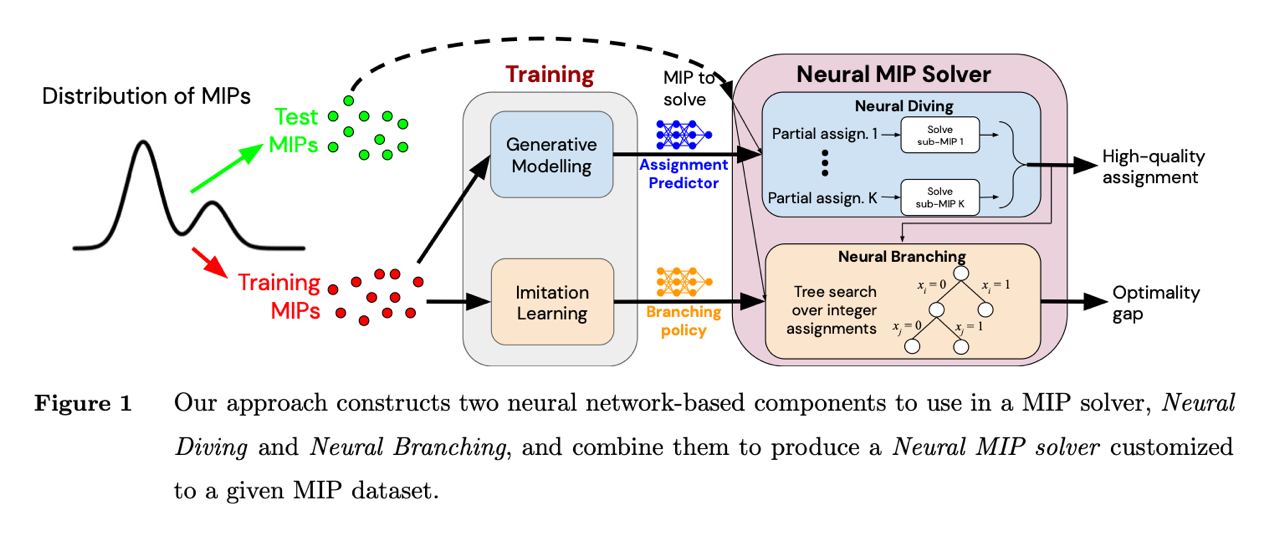
Article on speeding up Mixed Integer Programs with ML. Mixed Integer Programs are usually NP-hard problems:
- Problems solved with linear programming
- Production planning (pipeline optimization)
- Scheduling / Dispatching
Or any problems where integers represent various decisions (including some of the graph problems).
ArXiV: https://arxiv.org/abs/2012.13349
Wikipedia on Mixed Integer Programming: https://en.wikipedia.org/wiki/Integer_programming
#NPhard #MILP #DeepMind #productionml #linearprogramming #optimizationproblem
The Illustrated Retrieval Transformer
by @jayalammar
The latest batch of language models can be much smaller yet achieve GPT-3 like performance by being able to query a database or search the web for information. A key indication is that building larger and larger models is not the only way to improve performance.
http://jalammar.github.io/illustrated-retrieval-transformer/
#nlp #gpt3 #retro #deepmind
🔥16👍14❤2🤩1
🦜 Hi!
We are the first Telegram Data Science channel.
Channel was started as a collection of notable papers, news and releases shared for the members of Open Data Science (ODS) community. Through the years of just keeping the thing going we grew to an independent online Media supporting principles of Free and Open access to the information related to Data Science.
Ultimate Posts
* Where to start learning more about Data Science. https://github.com/open-data-science/ultimate_posts/tree/master/where_to_start
* @opendatascience channel audience research. https://github.com/open-data-science/ods_channel_stats_eda
Open Data Science
ODS.ai is an international community of people anyhow related to Data Science.
Website: https://ods.ai
Hashtags
Through the years we accumulated a big collection of materials, most of them accompanied by hashtags.
#deeplearning #DL — post about deep neural networks (> 1 layer)
#cv — posts related to Computer Vision. Pictures and videos
#nlp #nlu — Natural Language Processing and Natural Language Understanding. Texts and sequences
#audiolearning #speechrecognition — related to audio information processing
#ar — augmeneted reality related content
#rl — Reinforcement Learning (agents, bots and neural networks capable of playing games)
#gan #generation #generatinveart #neuralart — about neural artt and image generation
#transformer #vqgan #vae #bert #clip #StyleGAN2 #Unet #resnet #keras #Pytorch #GPT3 #GPT2 — related to special architectures or frameworks
#coding #CS — content related to software engineering sphere
#OpenAI #microsoft #Github #DeepMind #Yandex #Google #Facebook #huggingface — hashtags related to certain companies
#productionml #sota #recommendation #embeddings #selfdriving #dataset #opensource #analytics #statistics #attention #machine #translation #visualization
Chats
- Data Science Chat https://t.me/datascience_chat
- ODS Slack through invite form at website
ODS resources
* Main website: https://ods.ai
* ODS Community Telegram Channel (in Russian): @ods_ru
* ML trainings Telegram Channel: @mltrainings
* ODS Community Twitter: https://twitter.com/ods_ai
Feedback and Contacts
You are welcome to reach administration through telegram bot: @opendatasciencebot
GitHub
ultimate_posts/where_to_start at master · open-data-science/ultimate_posts
Ultimate posts for opendatascience telegram channel - open-data-science/ultimate_posts
👍57❤20🔥15🥰2👏2😁2🎉2⚡1👎1
Forwarded from Machinelearning
YouTube и Google DeepMind опубликовали статью и код фреймворка STATIC.
Проблема, которую он решает, хорошо знакома всем, кто строит рекомендательные системы на базе LLM: модель генерирует идентификаторы позиций, которых нет в каталоге, вышли из продажи или нарушают бизнес-правила. Именно поэтому YouTube выдает старые видео в ленте там, где должны появляться ролики последней недели.
Очевидное решение - префиксное дерево: на каждом шаге декодирования маска блокирует невалидные токены. Работает в целом нормально, но убивает производительность на TPU и GPU. Причины две:
В итоге префиксное дерево на CPU удваивает время инференса, что для системы с целевой задержкой ≤10 мс на шаг неприемлемо.
STATIC меняет подход принципиально: дерево разворачивается в статическую разреженную матрицу формата Compressed Sparse Row. Обход превращается в векторизованную операцию, которую акселератор умеет выполнять нативно.
Для первых двух уровней дерева, где коэффициент ветвления максимален, используется предвычисленная плотная булева маска: проверка валидности токена сводится к прямому обращению по индексу, без какого-либо перебора.
Для глубоких уровней работает специализированное ядро Vectorized Node Transition Kernel, оно читает фиксированный блок данных вне зависимости от реального числа дочерних узлов, не создавая условных переходов. В этом и есть вся соль: весь граф остается статическим, XLA не перекомпилирует ничего на ходу.
Замеры проводили на TPU v6e с 3B-моделью и словарем из 20 млн. свежих видео.
STATIC добился задержки 0,033 мс на шаг декодирования (это всего 0,25% от общего времени инференса.
Для сравнения: префиксное дерево на CPU давало +31,3 мс (239% от инференса), лучший из конкурирующих методов непосредственно на акселераторе, PPV Approximate +1,56 мс (11,9%). Итоговый профит:🟢 948x против дерева на CPU;🟢 47x против PPV Approximate;🟢 1033x против точного PPV.
По памяти: ~90 МБ на 1 млн. элементов. Для словаря в 20 млн. верхний предел по HBM примерно 1,5 ГБ, на практике - около 75% от этого значения.
A/B-тест с условием «только видео за последние 7 дней» показал +5,1% просмотров свежего контента, +2,9% для трехдневного окна, +0,15% по CTR и 100% соответствие бизнес-правилам.
Дополнительный бонус: метод решает проблему рекомендации новых товаров, не представленных в обучающей выборке. На датасете Amazon Reviews Recall@1 вырос с 0% до 1,2–4,4% в зависимости от категории.
В репозитории лежит ноутбук, на котором без утомительной настройки можно сразу посмотреть, как строится индекс из Semantic ID и как запускается декодирование с ограничениями.
@ai_machinelearning_big_data
#AI #ML #LLM #STATIC #DeepMind
Please open Telegram to view this post
VIEW IN TELEGRAM
Please open Telegram to view this post
VIEW IN TELEGRAM
❤4🔥2👍1🥰1
Forwarded from Machinelearning
Исследователи Google вместе с коллегами из нескольких университетов выкатили визионерский доклад, в котором пытаются понять, куда кривая вывезет, когда ИИ достигнет AGI и пойдет дальше
В основе - оценка от Epoch AI: за последние 10 лет эффективный компьют рос примерно в 10 раз за год (и это еще консервативно).
Отталкиваясь от этого, DeepMind выделяет 4 вектора перехода от AGI к ASI, которые вполне могут идти параллельно:
Во-первых, качественные тексты для претрейна и дотюна тупо заканчиваются, а железо и сами исследования дорожают каждый месяц.
Во-вторых, есть так называемый "барьер абстракции". Так как модели учатся на человеческих данных, далеко не факт, что они вообще способны порождать фундаментально новые концепты.
Ну и регуляторы в любой момент могут прийти и заколотить гвозядми инициативу.
Его инференс и логика всё равно останутся зажаты законами физики, теорией сложности и математикой (привет проблеме остановки и теоремам Гёделя о неполноте). ИИ не сможет просто по щелчку пальцев выдать нам лекарство от старения или сшить квантовую механику с общей теорией относительности.
Главный вывод в том, что надо готовиться к неопределенности.
Не будет одной волшебной кнопки и резкого прыжка в матрицу. Нас ждет серия локальных трансформаций, а может статься и так, что AGI окажется просто очередной фичей с импактом не больше, чем у появления смартфона или интернета.
@ai_machinelearning_big_data
#AI #ML #AGI #ASI #Research #DeepMind
Please open Telegram to view this post
VIEW IN TELEGRAM
❤5👍4🔥2🥰1🎉1